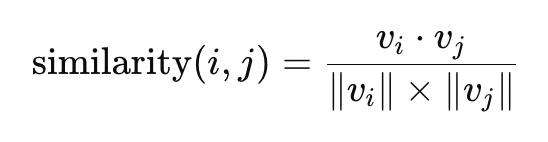> For the complete documentation index, see [llms.txt](https://docs.abtasty.com/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.abtasty.com/recommendations-and-merchandising/concepts/strategies/rules/presets-default-algorithms/algorithms-usage/semantic-similarity.md).
# Semantic Similarity
**Semantic similarity** measures how closely products are related in *meaning* — based on their text descriptions, attributes, and metadata — rather than behavioral signals.
#### How it is calculated
Each product description and metadata is encoded into a **dense vector (embedding)** using multilingual transformer models (e.g., SBERT, FastText).\
The algorithm computes the **cosine similarity** between product vectors:
Where:
* `v_i`, `v_j` = product embedding vectors
* Similarity ∈ \[0,1], with 1 meaning semantically identical.
#### Example
* Source product: *“Nike Air Zoom Pegasus 40 running shoe, red”*\
→ Semantically similar products might include:
* *“Adidas Ultraboost 22 running shoe, blue”* (same purpose and category)
* *“Salomon Speedcross trail shoe”* (related usage, similar function)
* ❌ *“Red dress”* (similar color but irrelevant meaning — model filters this out).
#### Multilingual model
The embedding model is trained on **109 languages**, including those without spaces (Japanese, Chinese, Thai, etc.), allowing semantic matching across all markets.\
This differs from the *Content Interest Criterion* used in the Segment Builder, which only supports Western languages.
#### Key takeaways
* Works from day one — no behavioral data needed.
* Ideal for new, long-tail, or low-traffic products.
* Enables “Similar products” and “Alternative discovery” strategies.
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://docs.abtasty.com/recommendations-and-merchandising/concepts/strategies/rules/presets-default-algorithms/algorithms-usage/semantic-similarity.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.